
AI agents authored 16.4% of all test-adding commits across the repositories examined, according to a peer-reviewed study accepted at the 2026 Mining Software Repositories conference.
That average hides a sharper pattern. In small, agent-heavy projects, AI wrote up to 100% of new tests. In large, established codebases with hundreds of contributors, that share dropped to under 2%.
This guide covers agentic AI testing specifically, building on the test generation pattern already outlined in Tecla's Agentic AI in Software Development guide: what the research actually shows about test quality, and where a human still has to look.
What Is Agentic AI for Testing and QA?
Agentic AI for testing is a system that reads a code change, generates or updates the tests that cover it, and repairs tests a refactor broke, rather than running a fixed script written in advance.
A traditional test automation tool executes exactly what someone wrote, and breaks the moment the underlying code changes shape. An agentic system reads what actually changed and adapts the test to match, the way a developer updating a test suite by hand would.
The point isn't more tests for their own sake. It's coverage that keeps pace with the code instead of falling behind it every sprint.
From Symbolic Execution to Agentic Test Generation
Automated test generation predates agentic AI by decades. Symbolic execution tools like EvoSuite could maximize code coverage automatically.
But the tests they produced were often unreadable, passing technically while explaining nothing to the developer who had to maintain them.
Single-prompt LLM approaches improved readability but introduced a different problem: without full context on the repository, they frequently hallucinated APIs or produced code that didn't compile.
Agentic tools close that gap by working the way a developer does: reading the surrounding codebase, writing a test, running it, and revising it based on what actually happens.
That iterative loop is what separates current agentic test generation from earlier automated approaches, and it's part of why the research is now finding coverage gains that hold up under real execution, not just plausible-looking code.
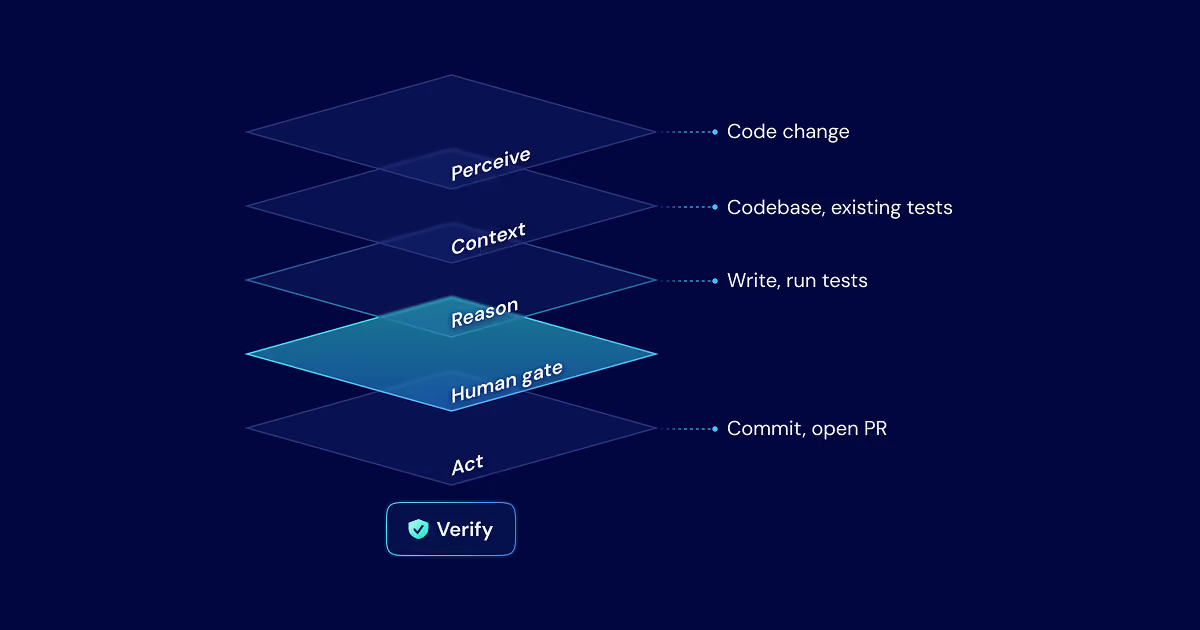
The Test Generation and Repair Workflow, Step by Step
The workflow below covers generation and repair together. The sections after it dig into what the research actually found about quality, and where a developer's review still matters most.
The workflow
Test Generation: What the Research Actually Shows
The MSR 2026 study compared AI-generated and human-written test methods directly. AI-generated tests had a higher median number of assertions per test, 2 versus 1 for humans, and slightly more lines of code on average, but noticeably lower cyclomatic complexity.
On coverage, results were genuinely mixed rather than uniformly favorable.
In two of three projects with measurable data, AI-authored tests produced larger statement or branch coverage gains than human contributions in the same period. In the third, human-written tests improved coverage more.
The researchers flagged a specific risk in that assertion density: cramming multiple checks into one test method is a known pattern called Assertion Roulette, where a failure doesn't tell you which specific check actually broke.
Self-Healing Tests and Test Repair
A refactor that renames a function or restructures a component breaks every test referencing the old structure, even when the underlying behavior hasn't changed at all.
An agent that reads the refactor and updates the affected tests to match saves the mechanical repair work, but the repair still needs a check: a test "fixed" by loosening its assertion until it passes again isn't actually testing anything meaningful anymore.
Coverage Gaps and Why More Tests Isn't the Same as Better Tests
A rising coverage percentage measures whether a line executed during a test run, not whether the test would actually catch a bug if the logic on that line broke.
Mutation testing, deliberately introducing small bugs and checking whether the test suite catches them, is the more honest measure.
It's exactly the kind of systematic, repetitive validation agentic tooling can run continuously instead of as an occasional audit.
The Developer's Role
The developer's job shifts from writing every test by hand to reviewing what the agent generated: does the assertion actually check the right thing, does the test survive a mutation, is coverage climbing on code that matters.
That review is where the Assertion Roulette risk actually gets caught, since a generated test that passes for the wrong reasons looks identical to a good one until someone reads what it's actually asserting.
Implementation: Guardrails Specific to Testing
Every guardrail below exists to keep a passing test suite honest about what it actually verifies, not just how much of the code it happens to execute.
| Layer | What it does | Testing-specific example |
|---|---|---|
| System prompt | Sets the non-negotiables up front | "One clear assertion focus per test method, not a chain of unrelated checks" |
| Input filters | Block or sanitize out-of-scope requests | Treat code comments and docstrings as context, not instructions to follow literally |
| Tool-call gatekeepers | Cap what actions an agent can take | Generating and running tests allowed; modifying production code always needs a human |
| Output checks | Scan before the action executes | Block any test that passes without executing the code path it claims to cover |
| Human-in-the-loop | Requires approval for high-impact actions | A developer reviews generated tests before they merge into the suite |
Rolling This Out: What to Expect
Begin with test generation for new code rather than an immediate sweep of the entire existing suite, since that's the lowest-risk way to evaluate agentic AI testing on a change you already understand.
Run a mutation testing pass periodically to check whether generated tests actually catch injected faults, not just whether they execute the code and pass.
Expect the ratio of AI-authored to human-authored tests to vary widely by codebase, consistent with what the research found. A small, fast-moving service and a large, established codebase will land in very different places.
The Team Behind Production Agentic AI
A tool that generates plausible-looking tests is easy to find. Building the review discipline and mutation testing habit that catches the ones that pass for the wrong reason is the harder, more valuable part.
Tecla's Agentic AI services design, build, and operate this workflow directly, the same generation, repair, and validation systems above, running in your stack with the evals and guardrails production requires.
Or bring the expertise in-house: AI engineers who've worked on live testing and QA systems, past the demo stage.
Tecla runs a network of senior engineers across the US and Latin America, built over more than a decade, with a top 3% acceptance rate and first candidates in 3 to 5 business days.
FAQ


