Builds semantic search and RAG systems using Pinecone for production applications. Has deployed vector databases at scale for multiple clients. Strong background in embedding optimization and retrieval architectures.
From prototype vector stores to production grade semantic search, Tecla connects you with vetted Pinecone developers who have built and shipped real AI systems. We build teams around your stack, your goals, and your delivery pace. Start interviewing in 5 days.


Builds semantic search and RAG systems using Pinecone for production applications. Has deployed vector databases at scale for multiple clients. Strong background in embedding optimization and retrieval architectures.

Experienced integrating Pinecone into search and recommendation features. Specializes in hybrid search patterns and metadata filtering. Has worked at SaaS companies building AI-powered products.

Backend engineer focused on vector database integration and API design. Comfortable deploying Pinecone in cloud environments. Has built search infrastructure for content and e-commerce platforms.

Works on embedding pipelines and document ingestion systems. Experience with batch and real-time vector indexing. Background in building data infrastructure for ML applications.

Full-stack developer building AI features into web applications. Has shipped semantic search and similarity features. Works across frontend interfaces and backend vector operations.

Builds document retrieval and question-answering systems. Learning production patterns for vector search optimization. Has worked on NLP projects and content recommendation features.
.avif)
Building production-ready semantic search and retrieval-augmented generation systems. Our Pinecone developers work with LangChain, LlamaIndex, OpenAI embeddings, and custom frameworks to deliver search features that actually work at scale.
Expert-level experience with embedding models, chunking strategies, metadata filtering, and hybrid search patterns. They design pipelines that process documents efficiently and return relevant results consistently.
Deep expertise in index configuration, query optimization, and namespace management. Plus advanced knowledge of caching strategies, batch operations, and monitoring to keep costs predictable.
Our Pinecone developers proactively monitor index health, optimize query performance, manage data updates, and handle scaling. They also provide architectural guidance to ensure your search features stay fast and reliable as data grows.

Share the specific skills, experience level, and tech stack you're looking for. We'll schedule a brief call to understand your requirements and timeline.

Within 3-5 days, receive a curated list of Pinecone developers who match your criteria. Every candidate has already passed our technical assessments and cultural fit evaluations.

Schedule interviews with the candidates you're most interested in. Assess their technical abilities, communication style, and how well they'd integrate with your team.

Extend an offer to your preferred candidate and start working together. We'll handle the paperwork and logistics so you can focus on integrating your new hire into the team.
We offer two approaches depending on whether you need individual contributors or a fully managed team.
Interview vetted Pinecone developers, expand your team flexibly, no long-term commitment required.
Fully managed AI team with dedicated technical leadership, integrated with your in-house staff for ongoing strategic work.
Pinecone developers build applications powered by vector databases for semantic search, recommendation systems, and retrieval-augmented generation. They integrate Pinecone into products and architect solutions that balance search quality with performance and cost.
Pinecone developers sit between backend engineering and ML infrastructure. They're not researchers training models, but they understand embeddings well enough to make intelligent decisions about chunking, indexing, and retrieval. Most work involves API integration, query optimization, and building systems around vector search.
They differentiate from full-stack developers through deep knowledge of how vector similarity works and what makes search results relevant. Unlike data scientists, they ship customer-facing features instead of experimental notebooks.
Companies hire Pinecone developers when moving beyond proof-of-concept into production. This happens after deciding vector search makes business sense but before knowing how to make it fast, accurate, and cost-effective for real users.
When you hire a Pinecone developer, AI search features stop being demos and start handling real traffic. Most companies see faster iteration and more predictable costs.
Prototype to Production: Turn working demos into reliable features that handle edge cases and don't break when document collections double overnight.
Cost Management: Monthly Pinecone costs drop 40-60% while maintaining search quality through query optimization and index configuration.
Search Quality: Focus on relevance and latency delivers results users actually click on, returned in under 500ms instead of 3 seconds.
Your job description filters for Pinecone engineers who've shipped vector search features, not completed tutorials. Make it specific enough to attract people who've debugged production relevance issues.
State whether you need someone to build RAG systems, optimize indexes, or own your search strategy. Include what success looks like: "Shipping product search handling 100K queries daily with sub-200ms latency" beats "building AI solutions."
Give context about your current implementation, data scale, and what's not working. Are you spending $5K/month on Pinecone with poor results? Help candidates understand if this matches problems they've solved.
List 3-5 must-haves that truly disqualify. "Built production vector search handling 10K+ daily queries" is specific. "Experience with AI" is worthless. Include years with tools (Pinecone, LangChain) and outcomes (improved relevance, reduced costs).
Separate required from preferred so strong candidates don't rule themselves out. Describe your actual environment: Pinecone serverless or self-hosted? Remote-first async or real-time pairing?
Tell candidates to send a brief description of the most complex vector search system they built and what broke in production. This filters for people who've shipped real features.
Set timeline expectations: "We'll respond within 5 business days and schedule first interviews within 2 weeks" beats radio silence.
Good questions reveal how candidates think about search relevance, cost management, and production reliability. Not surface-level knowledge.
Understanding of chunking strategies, embedding model trade-offs, and how metadata filtering improves results. Listen for specific decisions about namespace design and hybrid search patterns.
What it reveals: Hands-on troubleshooting beyond "adjust embeddings." Look for analyzing query patterns, testing chunking strategies, A/B testing metadata filters, measuring relevance improvements.
What it reveals: Whether they own outcomes or execute tasks. Listen for ownership of metrics like search relevance, query latency, cost per query. Strong candidates explain edge cases and monitoring.
What it reveals: How they debug under uncertainty and learn from failures. Look for honesty about what went wrong, specific debugging techniques, and safeguards added.
What it reveals: Strategic thinking about cost-quality trade-offs. Watch for frameworks around when search quality justifies higher costs versus when good-enough works.
What it reveals: Collaborative problem-solving and communication style. Listen for partnership mindset, not gatekeeping. Strong candidates educate stakeholders and help teams make informed decisions.
What it reveals: Honest self-assessment about what energizes them. Neither answer is wrong, but helps identify mismatches. Strong candidates know what they're good at and what drains them.
LATAM: $100K-$135K depending on seniority. US: $246K-$332K+ for same experience. That's 45-59% savings. The difference is cost of living, not skill—these Pinecone engineers work with the same APIs, embedding models, and search architectures. Many LATAM Pinecone developers have built production vector search systems for US companies.
One senior nearshore Pinecone developer: save $111K-$197K annually. A team of 5: save $729K-$986K+ total. Savings come from lower salaries, no US benefits overhead, reduced recruiting fees, and faster hiring. The 97% retention rate prevents constant rehiring costs that would otherwise compound over time.
Yes. LATAM Pinecone developers build with the same Pinecone APIs, LangChain, LlamaIndex, and OpenAI embeddings. They've architected semantic search, optimized indexes, and debugged production issues. 85%+ are fluent in English. Cost reflects regional economics—a senior Pinecone developer in Buenos Aires costs $100K-$125K versus $240K-$280K in San Francisco.
Yes. 30-90 day trials to evaluate fit with nearshore Pinecone developers. Contract-to-hire starting with specific features. Project-based work with defined scope. Staff augmentation for long-term flexibility. Our 90-day guarantee means if technical fit isn't right, we replace them at no cost.
US hiring includes 35-45% benefits overhead, 10-15% recruiting fees, onboarding, stock options, and turnover risk (4-6 months salary). Nearshore Pinecone developers through Tecla eliminate most of these with transparent rates and 97% retention. One monthly rate covers everything.
Traditional: 6-12 weeks (sourcing, screening, interviews, negotiation, notice period). Tecla: 2-3 weeks total. You hire 4-10 weeks faster. While competitors spend months sourcing candidates, you're onboarding a nearshore Pinecone engineer who starts building your semantic search system next week.
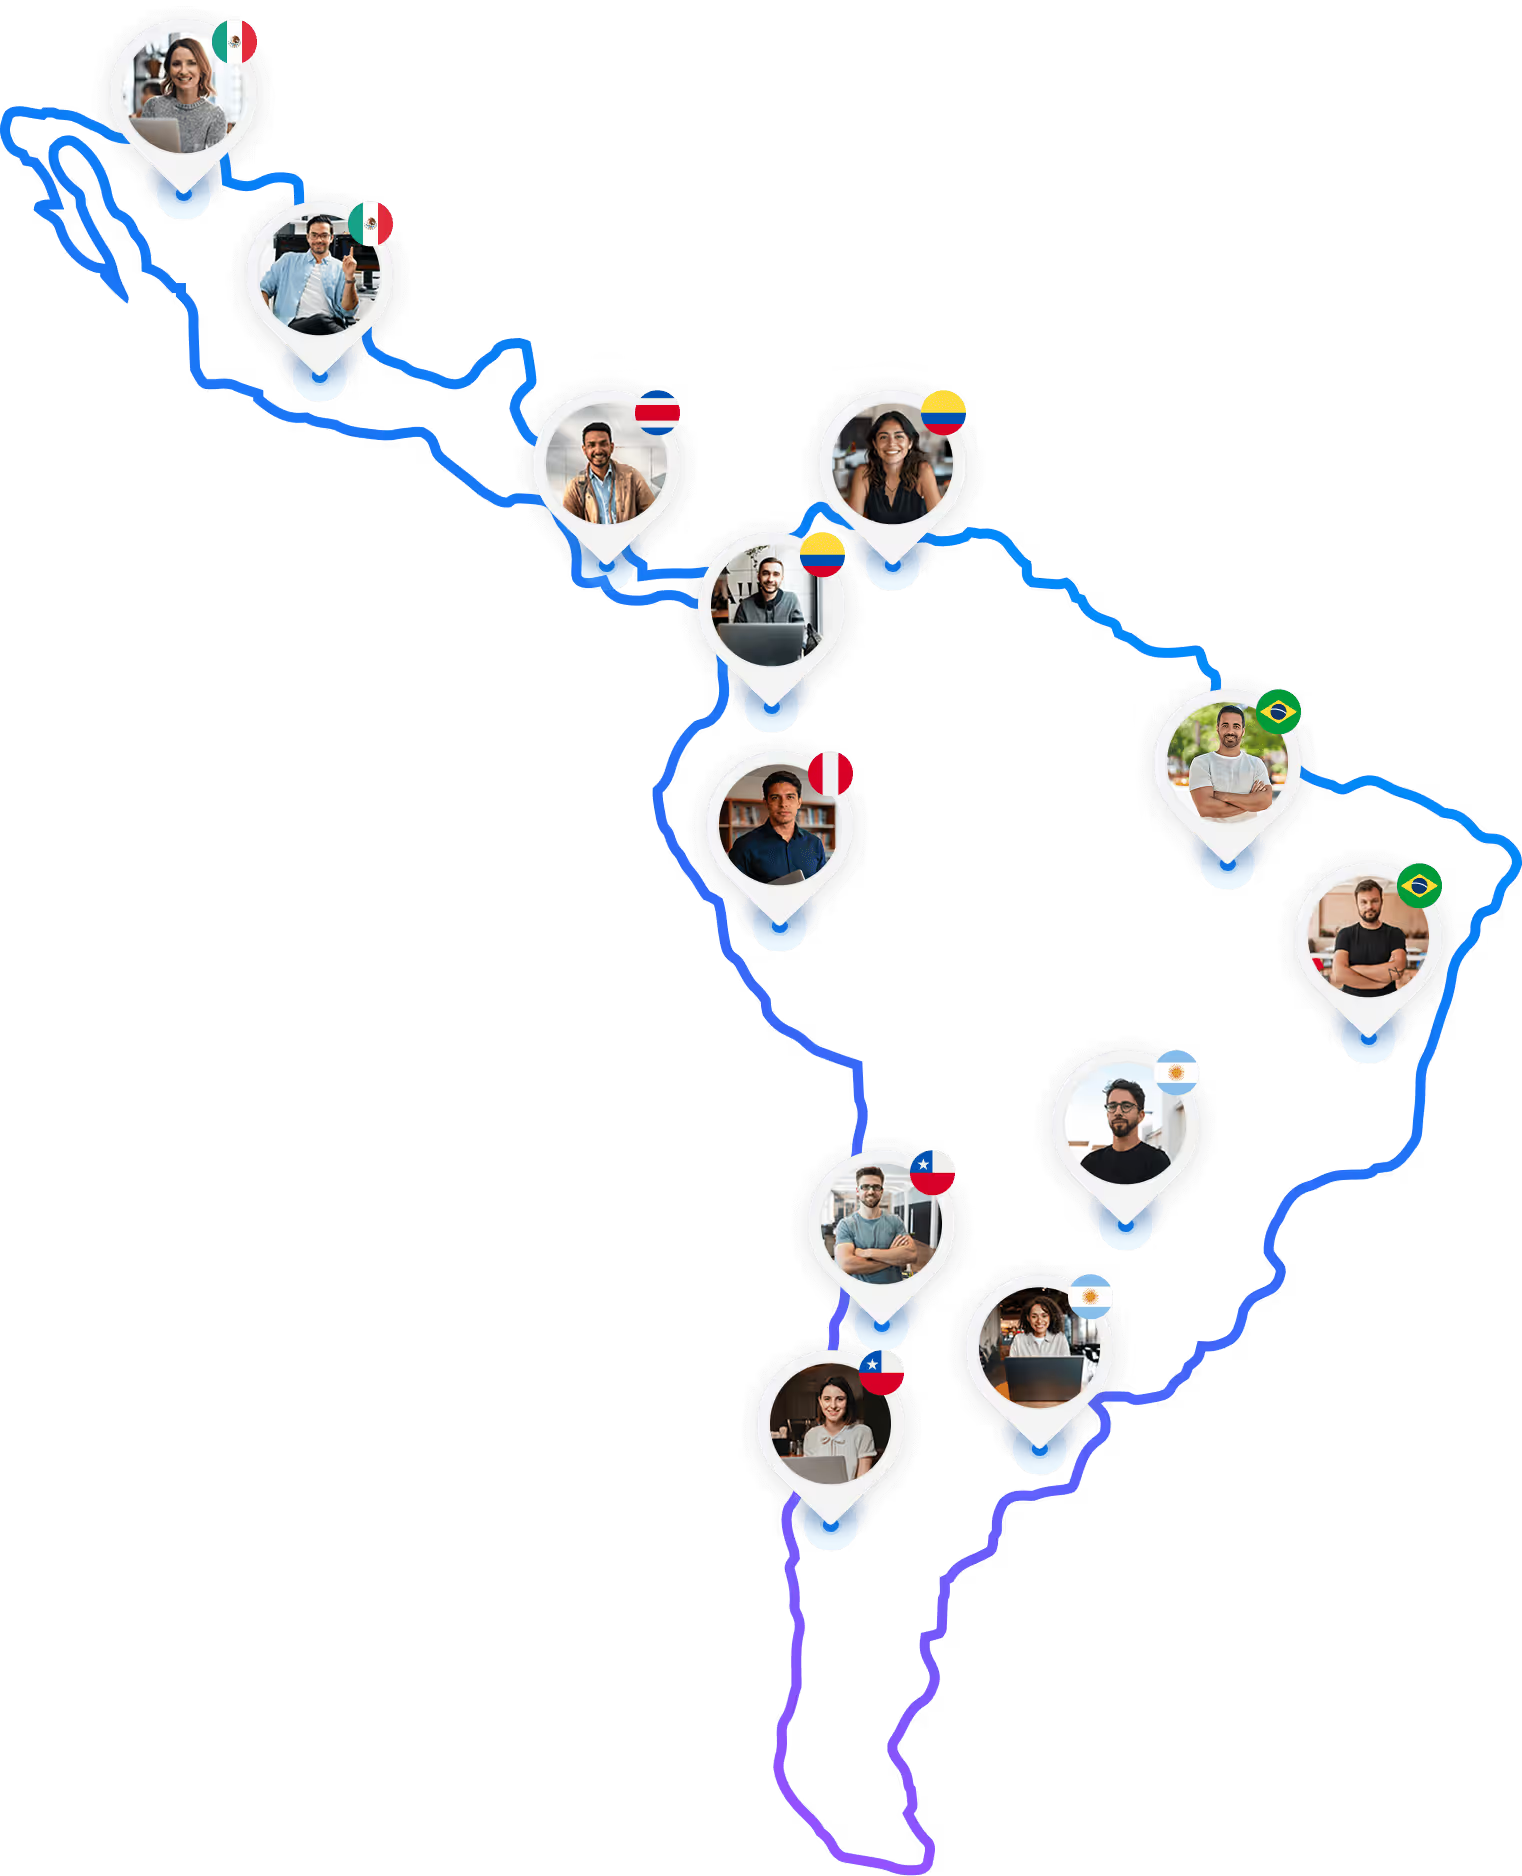
Connect with Developers from Latin America in 5 days. Same expertise, full timezone overlap, 50-60% savings.