Built predictive models improving customer retention by 40% for SaaS platforms. Specializes in deep learning and feature engineering. Previously led ML initiatives at a Series B fintech startup.
Whether you're running early stage experiments or scaling production AI systems, Tecla gives you access to a vetted pool of AI data scientists who turn complex data into real business outcomes. Start interviewing in 5 days.
.avif)

Built predictive models improving customer retention by 40% for SaaS platforms. Specializes in deep learning and feature engineering. Previously led ML initiatives at a Series B fintech startup.

Designed recommendation systems processing 5M+ daily predictions. Expert in A/B testing and model deployment at scale. Reduced churn prediction error by 35% through ensemble methods.

Architected AI solutions for document processing and image classification. Deep expertise in transformer models and transfer learning. Published research in top ML conferences.

Built forecasting models for supply chain optimization saving $2M annually. Specializes in time series analysis and causal inference. Strong communication with business stakeholders.

Deployed production ML systems handling 10M+ daily inferences. Expert in model monitoring and automated retraining pipelines. Cut model deployment time from weeks to days.

Led data science teams building revenue optimization models. Specializes in experimentation design and business impact measurement. Advised C-suite on AI strategy for Fortune 500 clients.
.avif)
Our AI data scientists build and validate machine learning models for classification, regression, forecasting, and recommendation systems. They work with scikit-learn, TensorFlow, PyTorch, and XGBoost. Expect rigorous experimentation with proper train/test splits, cross-validation, and statistical significance testing.
Expert-level experience transforming raw data into features that improve model performance. They design data pipelines using Spark, Pandas, and SQL. These pipelines handle missing data, outliers, and feature scaling properly instead of breaking on real-world messiness.
Deep expertise deploying models to production using MLflow, Docker, Kubernetes, or cloud ML services. They implement monitoring for model drift, set up automated retraining, and build APIs that serve predictions reliably. Your models work in production, not just notebooks.
Our AI data scientists translate model results into business recommendations. They design A/B tests to measure impact, create visualizations stakeholders understand, and communicate uncertainty appropriately. They know shipping a good model beats perfecting one that never deploys.

Share the specific skills, experience level, and tech stack you're looking for. We'll schedule a brief call to understand your requirements and timeline.

Within 3-5 days, you'll see profiles matched to your requirements. Every candidate has passed technical assessments covering statistics, ML algorithms, and coding. We've verified they've shipped production models, not just Kaggle competitions.

Talk to candidates who fit your needs. See how they approach model selection, explain their methodology, and think about measuring business impact versus just accuracy metrics.

Pick your AI data scientist and start building. We handle contracts and logistics so you can focus on getting them access to your data and aligned with your product goals.
An AI data scientist builds machine learning models that solve business problems using data. Think of them as the bridge between raw data and automated decision-making. They don't just analyze data, they build systems that learn from it. The difference from traditional data analysts? AI data scientists write code that trains models, deploy those models to production, and measure their real-world impact. They combine statistics, programming, and business judgment to decide which problems ML can actually solve. These professionals sit at the intersection of software engineering, statistics, and domain expertise. They're not just running algorithms from libraries. They're choosing appropriate methods, validating assumptions, and building systems that work reliably with new data. Companies hire AI data scientists when they're moving from manual analysis to automated prediction, scaling personalization beyond human capability, or optimizing decisions that happen too fast for human intervention. The role evolved as ML moved from research labs into production systems powering real products.
When you hire AI data scientists, you automate decisions that currently require human judgment at scale. Most companies see 20-40% improvements in key metrics through better prediction, personalization systems that actually convert, and operational efficiency from optimizing processes humans can't track.
Running ML experiments in notebooks that never reach production? Good data scientists build deployment pipelines, monitor model performance, and set up automated retraining. Your models improve continuously instead of becoming stale six months after launch.
Here's where the ROI becomes obvious. Manual credit risk assessment approving 100 applications per day? ML models review 10,000 per day with lower default rates. Product recommendations based on category browsing? Personalized models increase conversion 30-50%. Inventory planning based on last year's numbers? Forecasting models adapt to trends and reduce waste.
Your data team builds great dashboards but can't predict what happens next? Data scientists build models that forecast demand, predict churn, identify high-value leads, or detect fraud before it impacts revenue. These aren't insights, they're automated actions.
Your job description either attracts engineers who've built production vector search systems or people who followed a LangChain tutorial once. Be specific enough to filter for actual Chroma experience and real RAG implementation.
State whether you need RAG pipeline development, vector database optimization, or full-stack AI integration. Include what success looks like: "Reduce answer latency to under 200ms for 95th percentile queries" or "Improve retrieval precision from 0.6 to 0.8+ within 90 days."
Give real context about your current state. Are you migrating from Pinecone? Building your first RAG system? Scaling from 100K to 10M embeddings? Candidates who've solved similar problems will self-select. Those who haven't will skip your posting.
List 3-5 must-haves that truly disqualify candidates: "2+ years production experience with vector databases," "Built RAG systems handling 1M+ queries/month," "Optimized embedding pipelines reducing latency by 50%+." Skip generic requirements like "strong Python skills." Anyone applying already has those.
Separate required from preferred so strong candidates don't rule themselves out. "Experience with Chroma specifically" is preferred. "Experience with any production vector database (Chroma, Pinecone, Weaviate, Milvus)" is required.
Describe your actual stack and workflow instead of buzzwords. "We use FastAPI, deploy on AWS ECS, run async embedding jobs with Celery, and do code review in GitHub. Daily standups at 10am EST, otherwise async communication in Slack" tells candidates exactly what they're walking into.
Tell candidates to send you a specific RAG system they built, the retrieval metrics before/after their optimizations, and the biggest technical challenge they solved. This filters for people who've shipped actual systems versus those who played with notebooks.
Set timeline expectations: "We review applications weekly and schedule technical screens within 5 days. Total process takes 2-3 weeks from application to offer." Reduces candidate anxiety and shows you're organized.
Good interview questions reveal production experience versus academic knowledge.
What it reveals: Strong candidates start with understanding the business objective, not jumping to algorithms. They discuss defining success metrics, checking if ML is needed, data exploration, baseline models, evaluation strategy, and deployment considerations. Listen for business thinking, not just technical skills.
What it reveals: This separates people who understand ML fundamentals from those who just run libraries. Good answers explain underfitting (high bias) versus overfitting (high variance), mention cross-validation for detection, and discuss regularization, ensemble methods, or getting more data as solutions.
What it reveals: Experienced data scientists immediately mention precision, recall, F1, ROC-AUC, and why accuracy fails with imbalanced data. They connect metrics to business context (false positives versus false negatives having different costs). Watch for understanding that model evaluation depends on the use case.
What it reveals: Practical candidates check for data drift (input distribution changed), concept drift (relationships changed), data quality issues, or bugs in the pipeline. They mention monitoring systems that would catch this early. This shows production ML thinking versus just training models.
What it reveals: Strong answers discuss transfer learning, semi-supervised methods, active learning to label strategically, data augmentation, or simpler models that work with less data. Avoid candidates who immediately suggest "just get more data" without exploring technical solutions.
What it reveals: Their war stories show what they've learned. Good answers explain specific failures (train-test data leakage, distribution shift, latency issues, incorrect business logic) and what they did to fix it. Candidates without production experience struggle here.
What it reveals: Experienced data scientists acknowledge simpler methods often work better. They discuss when deep learning makes sense (unstructured data, complex patterns, lots of data) versus when it's overkill. This reveals judgment about tool selection, not just knowing buzzwords.
What it reveals: Good answers mention SHAP values, feature importance, example predictions, ablation tests showing impact, or building trust through consistent A/B test wins. They understand their job includes making models understandable, not just accurate.
What it reveals: This shows whether they've actually deployed models. Common answers include latency requirements, handling missing features at inference time, versioning, monitoring, and different languages (Python notebooks versus production Java). Listen for collaborative approach.
What it reveals: Neither answer is wrong. But if you need production ML and they only want research, that's a mismatch. If you're building research capabilities and they only want proven methods, also a mismatch. Watch for self-awareness about preferences.
What it reveals: Strong candidates discuss recommending simpler approaches when appropriate, knowing ML isn't always the answer. They give examples of using rules, heuristics, or simple statistics instead of complex models. This shows business judgment over technical ego.
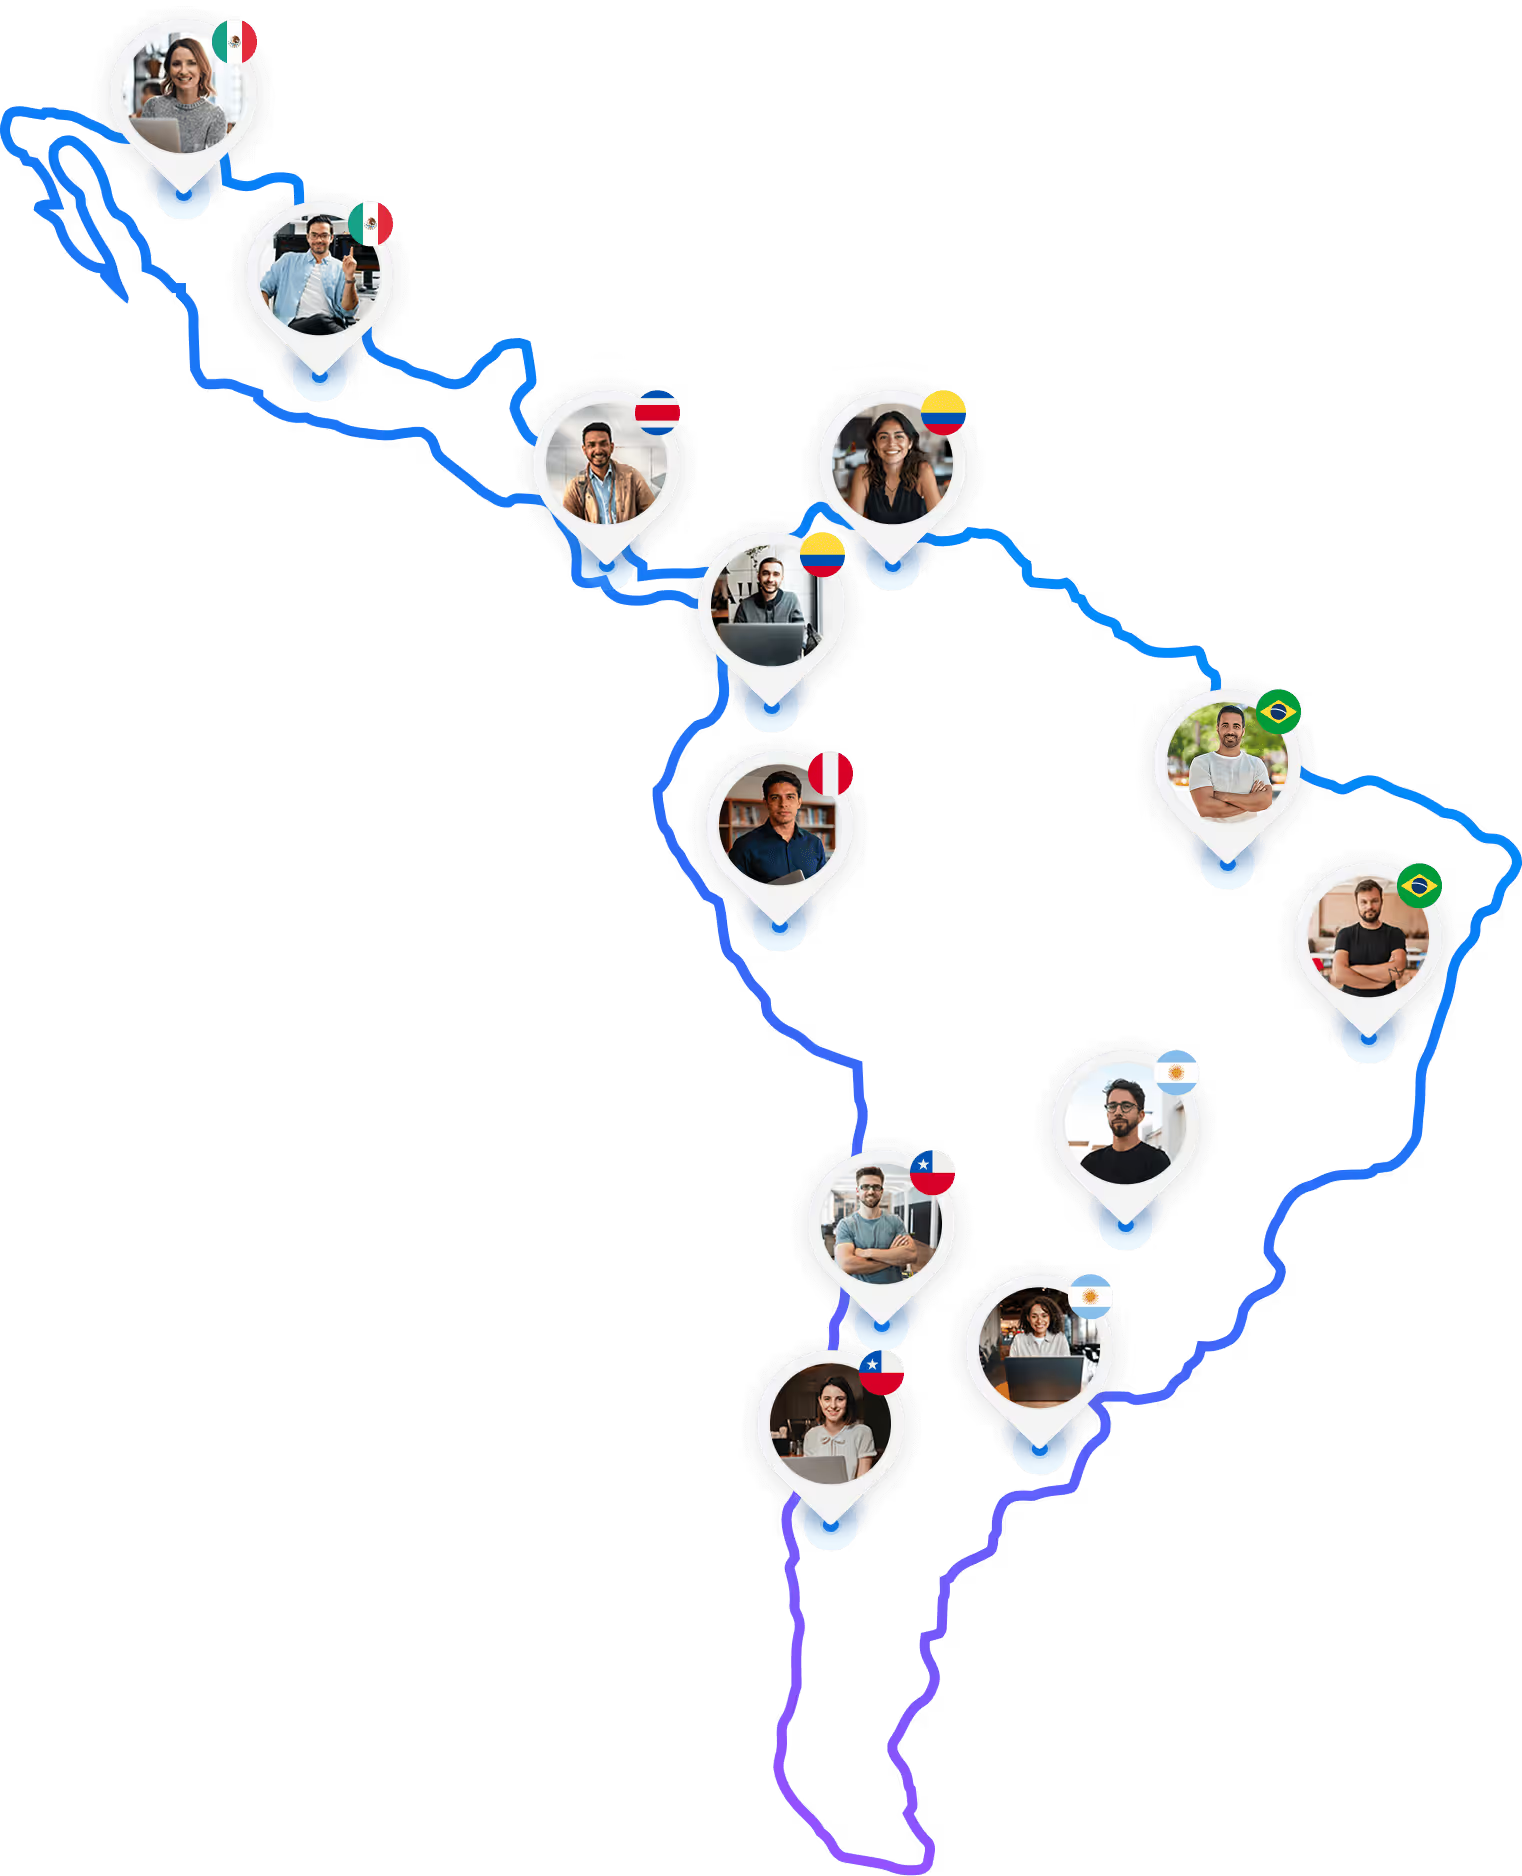
Connect with senior AI data scientists from Latin America in 5 days. Same expertise, full timezone overlap, 50-60% savings.