Hire LlamaIndex Developers

Every LlamaIndex developer in our network is vetted for technical depth, communication, and real world delivery. Whether you're prototyping RAG architectures or scaling LLM powered applications to production, Tecla builds you a team that fits your stack and moves at your pace. Start interviewing in 5 days.

  • 97% Retention
  • 5-Day Average Placement
  • Top 3%

Trusted by leading companies

LlamaIndex Developers Ready to Start

Man with glasses holding a laptop, surrounded by icons of Python logo, llama silhouette, and a flowchart document.
Tomás A., Senior AI Engineer
Tomás A.
Senior AI Engineer
Argentina
7+ years

Builds enterprise RAG systems using LlamaIndex to connect LLMs to structured and unstructured business data. Deep experience with index construction, query engines, and retrieval optimization for knowledge-intensive applications. Has shipped AI search and Q&A products for legal and financial services clients.

Skills
LlamaIndex
Python
OpenAI
Pinecone
Carolina F., AI Solutions Engineer
Sofía M.
LLM Integration Engineer
Colombia
5+ years

Designs LlamaIndex-powered pipelines for document ingestion, semantic search, and multi-step reasoning. Specializes in building routers, sub-question query engines, and hybrid retrieval strategies. Background in developing AI assistants for enterprise knowledge management platforms.

Skills
OpenAI
Function Calling
FastAPI
PostgreSQL
Andrés L., Senior ML Engineer
Rodrigo F.
Senior AI Developer
Mexico
8+ years

AI developer focused on LlamaIndex agent frameworks and data connectors for complex enterprise environments. Comfortable integrating LlamaIndex with SQL databases, APIs, and proprietary document stores. Has built production AI systems for healthcare and professional services organizations.

Skills
LlamaIndex
Python
Weaviate
LangChain
Isabela T., AI Developer
Juliana C.
ML Engineer
Brazil
5+ years

Builds multi-modal RAG pipelines using LlamaIndex for document-heavy applications. Specializes in custom node parsers, metadata filtering, and evaluation frameworks for measuring retrieval accuracy. Experience building AI tooling for content-rich SaaS platforms.

Skills
LlamaIndex
Python
Azure OpenAI
PostgreSQL + pgvector
Felipe R., Full-Stack AI Engineer
Pablo E.
AI Infrastructure Engineer
Chile
4+ years

Infrastructure-focused AI engineer deploying LlamaIndex applications at scale on AWS. Has designed async indexing pipelines, managed index freshness for frequently-updated data, and optimized query latency for high-traffic RAG endpoints.

Skills
LlamaIndex
Python
Cohere
Qdrant
Luciana P., AI Developer
Luciana P.
AI Developer
Uruguay
3+ years

Builds LlamaIndex-based applications for document Q&A and structured data retrieval. Experience designing custom data loaders, chunking strategies, and retrieval evaluation workflows. Working on advanced agent architectures with LlamaIndex’s agent framework.

Skills
LlamaIndex
Python
ChromaDB
FastAPI
See How Much You'll Save
LlamaIndex Developer
United States flag
US HIRE
$
259
k
per year
Map of Latin America
LATAM HIRE
$
102
k
per year
Your annual savings
$157k
per year
60.6%

Why Companies Choose Tecla For LlamaIndex Developer Hiring

  • Price reduction icon

    Save 40–60% on Salaries

    Hiring nearshore LlamaIndex developers in Latin America costs significantly less than US-based equivalents. The RAG expertise is the same. The salary baseline reflects where they live, not what they know.

  • Faster Hiring Process

    5-Day Candidate Match

    Most companies spend the first three weeks of a search just sourcing. We skip that. You have qualified LlamaIndex developer profiles within 5 days of telling us what you need.

  • We focus exclusively on Latin America

    Zero Timezone Friction

    Latin American developers work within 0–3 hours of US time. When a retrieval quality issue surfaces during a product sprint, you get a response the same day, not the next morning.

  • Group of people icon

    97% Retention After Year One

    LlamaIndex developers who understand your index architecture, query engine design, and data connectors are hard to rebuild from scratch. Our retention rate means that institutional knowledge compounds rather than cycling out.

  • nearshore icon

    Top 3% Acceptance Rate

    The developers you interview passed technical evaluations covering LlamaIndex architecture, retrieval design, and production deployment before you saw their name. One hundred apply. Three get through.

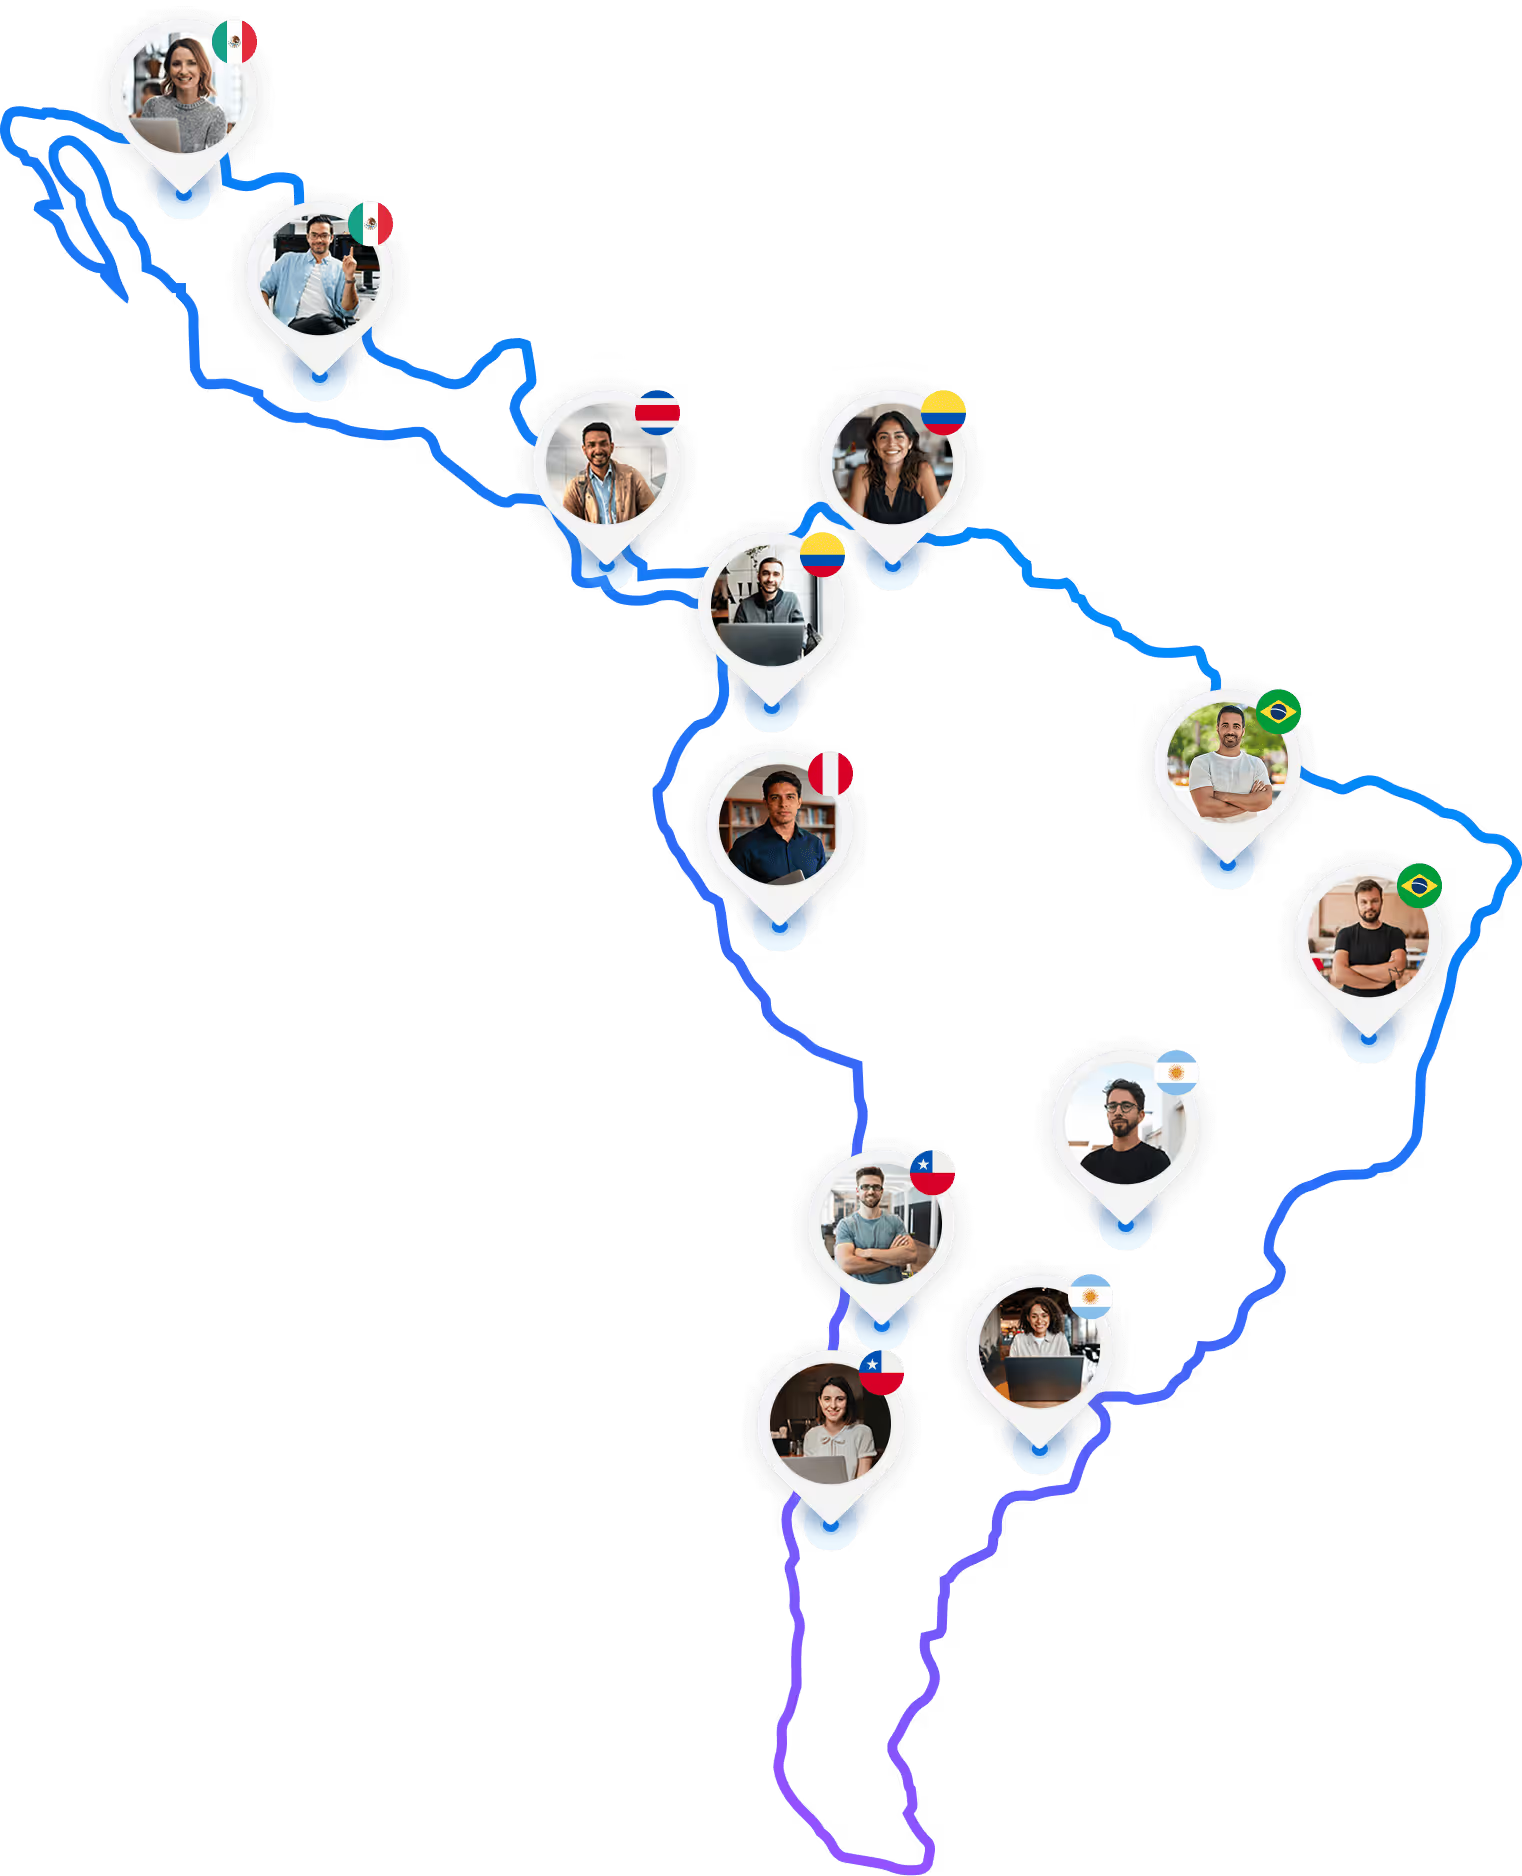
Map of Latin America with location pins showing diverse people in Mexico, Costa Rica, Colombia, Peru, Brazil, Argentina, and Chile.

Companies That Hired Through Tecla

"Tecla successfully found candidates for our team and handled the entire process from scheduling to interviews. They were timely, responsive, and always kept communication flowing through email and messaging apps. I was really impressed with Tecla’s follow-up and thoroughness throughout the process."

Jessica WarrenHead of People @ Chowly

"I’m very happy with Tecla. Their support has improved our QA process, reduced bug reports by half, and made our onboarding process twice as fast. The team is responsive, cost-effective, and delivers high-quality candidates on time. Tecla has truly become a trusted extension of our internal hiring team."
Meit ShahPrincipal PM @ Stash

"Tecla is organized and provides a strong partnership experience. From hiring multiple engineers within weeks to maintaining consistent communication and feedback, they’ve shown real professionalism. Their follow-up and collaboration made the entire staffing process efficient and enjoyable."

Kristen MarcoeDirector, People & HR @ Credo AI

The Capabilities We Screen For in All LlamaIndex Developers

IT

RAG Pipeline Design & Optimization

Building retrieval-augmented generation systems using LlamaIndex’s index types, query engines, and retrieval modes for accurate, scalable document Q&A. Our LlamaIndex developers work with VectorStoreIndex, SummaryIndex, KnowledgeGraphIndex, and custom retrievers to build pipelines that return relevant context and reduce hallucination rates.

AI icon

Data Ingestion & Index Architecture

Expert-level experience with LlamaIndex data connectors, document loaders, node parsers, and metadata extraction across PDFs, databases, APIs, and proprietary data formats. They design ingestion pipelines that keep indexes current and structure document relationships in ways that improve downstream retrieval quality.

AI robot icon

Agent & Multi-Step Reasoning Frameworks

Deep expertise building LlamaIndex agents, sub-question query engines, router query engines, and tool-calling workflows for complex multi-step AI tasks. Plus advanced capability in query transformations, hypothetical document embeddings, and hybrid search approaches that combine semantic and keyword retrieval.

ETL icon

Evaluation, Monitoring & Production Readiness

Our LlamaIndex developers proactively track retrieval faithfulness, answer relevance, and context precision using evaluation frameworks, monitor query latency and index freshness, handle embedding model updates, and manage vector store performance at scale. They also build observability tooling so your team can measure RAG quality without inspecting individual query traces manually.

Ready to hire faster?

Get Started With Tecla

Interview vetted developers in 5 days

Getting Started With Tecla in 4 Simple Steps

  1. Woman with long hair holding a pen talking to a man at a wooden table in an office.

    Define What You Need

    Share your project goals, required experience level, and hiring timeline. We’ll arrange a brief call to understand your expectations and team setup.

  2. Collage of diverse individuals smiling and working with laptops in various indoor and outdoor settings.

    Review Candidate Profiles

    Within 3–5 business days, you’ll receive a shortlist of LlamaIndex developers who align with your criteria. All candidates are pre-screened for relevant experience and strong communication skills.

  3. Man smiling and holding pen during a business meeting with a laptop showing sales charts nearby.

    Interview and Assess

    Meet your preferred candidates to evaluate their background, working style, and overall fit with your team. We support coordination to keep the process efficient.

  4. Two people shaking hands over a wooden desk with a laptop, agreement, and coffee cup nearby.

    Start Working Together

    Choose your developer and begin the engagement. We’ll handle contracts, compliance, and administrative logistics so you can stay focused on delivering results.

Our Hiring Models

Two ways to build your LlamaIndex development capacity.

Staff Augmentation

Add individual nearshore LlamaIndex developers to your existing team. Interview vetted candidates, hire who fits, and scale without long-term contract obligations.

Nearshore Teams

A fully managed AI development team with technical leadership built in. Designed for organizations running ongoing LlamaIndex development that needs dedicated capacity integrated with internal product and engineering teams.

True Cost to Hire LlamaIndex Developers: US vs. LATAM

LlamaIndex expertise sits in a narrow band of applied AI engineering that commands premium compensation in US markets. Total hiring investment depends heavily on location. ‍ Beyond what a US developer earns, full-time hires carry substantial overhead: healthcare, retirement matching, payroll obligations, and recruiting costs that typically add 35–45% to base compensation.

United States flagUS Full-Time Hiring: Hidden Costs

Senior LlamaIndex developers in US tech markets command $180K–$250K base. The fully-loaded cost is substantially higher.

  • Health insurance: $12K–$18K
  • Retirement contributions: $10.8K–$15K (~6% of base)
  • Payroll taxes: $14.4K–$20K (~8% of base)
  • PTO: $9K–$12.5K (~5% of base)
  • Administrative costs: $6K–$9K
  • Recruitment costs: $27K–$37.5K (~15% of base)

Total hidden costs: $79.2K–$112K per developer

Adding base compensation brings total annual investment to $259.2K–$362K per LlamaIndex developer.

Map of Latin AmericaLATAM Hiring Through Tecla (Per Developer, Annually)

All-inclusive rate: $102K–$144K

One monthly rate covers developer compensation, regional benefits, payroll taxes, paid time off, HR administration, technical screening, legal setup, and ongoing engagement management. No recruiting markup. No hidden line items at renewal.

Your LlamaIndex developer is in your codebase and building retrieval pipelines while you concentrate on what the product needs, not on employment administration.

The Real Savings

A senior LlamaIndex developer in the US costs $259.2K–$362K annually once overhead is included. Tecla's all-inclusive rate: $102K–$144K. That's $115.2K–$218K saved per developer (44–60% reduction). ‍A team of 5: $1.3M–$1.81M annually in the US versus $510K–$720K through Tecla. Annual savings: $790K–$1.09M, with the same RAG architecture depth, English fluency, and timezone alignment. Transparent all-inclusive pricing from day one. No recruiting fees or placement costs. Resources replaceable at no cost during the 90-day trial period.

What Is a LlamaIndex Developer?

LlamaIndex developers build the data infrastructure that connects large language models to real business knowledge. They design ingestion pipelines, construct indexes, build query engines, and deploy RAG systems that let AI applications answer questions accurately using company-specific data.

LlamaIndex developers work at the intersection of data engineering and applied AI. They're not training models, but they determine whether a model's outputs are grounded in accurate, relevant information.

What differentiates a strong LlamaIndex developer from someone who followed a tutorial is their ability to diagnose why retrieval fails. Chunk sizes that lose context. Embedding models that don't match the domain. Query engines that return superficially relevant but factually wrong results. These problems only show up in production.

Companies hire LlamaIndex developers when internal AI experiments have shown that simply prompting GPT-4 isn't enough, often after Objective-C developers or other mobile teams have already flagged that the AI responses aren't accurate enough for their applications.

Business Impact

When you hire a LlamaIndex developer, AI applications stop returning generic answers and start pulling accurate, specific information from your actual data.

Answer accuracy: Proper RAG pipeline design with relevant chunking, metadata filtering, and reranking reduces hallucination rates significantly compared to naive retrieval approaches.

Indexing performance: Optimized ingestion pipelines and index architecture mean new documents appear in search results within minutes rather than after manual batch updates.

Multi-step reasoning: Agent frameworks and sub-question query engines let AI handle complex queries that require combining information from multiple sources rather than retrieving a single chunk.

System reliability: Evaluation frameworks tracking faithfulness and relevance catch retrieval quality degradation during development, before it reaches users.

Frequently asked questions

How much does it cost to hire LlamaIndex developers from LatAm vs the US?

LATAM: $102K–$144K depending on seniority. US: $259K–$362K+ for equivalent experience. That's 44–60% savings. Nearshore LlamaIndex developers work with the same index architectures, retrieval strategies, agent frameworks, and vector store integrations. Many have shipped production RAG systems for US companies. The cost difference reflects regional economics, not technical capability.

How much can I save per year hiring nearshore LlamaIndex developers?

One senior hire: save $115K–$218K annually. A team of 5: save $790K–$1.09M+ per year. Savings come from lower regional compensation, no US benefits overhead, eliminated recruiting fees, and faster time-to-hire. The 97% retention rate means you're not rebuilding your RAG expertise from scratch after year one.

How does Tecla's process work to hire LATAM LlamaIndex developers?

Post requirements (Day 1). Review pre-vetted candidates (Days 2–5). Interview matches (Week 1–2). Hire and onboard (Week 2–3). Total: 2–3 weeks versus 6–12 weeks with traditional recruiting. Speed comes from a vetted developer pool of 50K+, which eliminates the sourcing delay that consumes the first third of most hiring timelines.

Do LATAM LlamaIndex developers have the same skills as US developers?

Yes. Latin American LlamaIndex developers build with the same index types, query engine architectures, agent frameworks, and vector store integrations. 85%+ are fluent in English. A senior LlamaIndex developer in Santiago costs $102K–$130K annually, and software developers in Brazil follow similar regional pricing. The same profile in New York runs $260K–$340K.

Can I hire nearshore LlamaIndex developers on a trial basis?

Yes. 30–90 day trials to evaluate technical fit and how they integrate with your team. Contract-to-hire starting with a defined RAG project. Project-based work with scoped deliverables. Staff augmentation for sustained development. Our 90-day guarantee means if the technical fit isn't right, we replace them at no additional cost.
What hidden costs should I consider when hiring LlamaIndex developers?

US hiring includes 35–45% benefits overhead, 10–15% recruiting fees, onboarding investment, equity expectations, and turnover risk worth 4–6 months of salary. Hiring nearshore LlamaIndex developers through Tecla removes most of that. One transparent monthly rate, developers manage their own regional benefits, and 97% retention keeps your RAG institutional knowledge intact year over year.

How quickly can I hire nearshore LlamaIndex developers through Tecla?

Traditional recruiting: 6–12 weeks from job post to first day. Tecla: 2–3 weeks total. You hire 4–10 weeks faster. While other companies are still writing job descriptions, you're onboarding a nearshore LlamaIndex developer who starts building your retrieval pipelines next week.

Have any questions?

Schedule a call to discuss in more detail.

Book a call

Ready to Hire LlamaIndex Developers?

Connect with Developers from Latin America in 5 days. Same expertise, full timezone overlap, 50-60% savings.