
Maintainer merge decisions run about 24 percentage points below automated benchmark scores on SWE-bench Verified, according to a study by the AI research nonprofit METR.
The more striking number is the baseline. Even original, human-written reference patches, the ones the benchmark itself considers correct, only get merged by real maintainers 68% of the time.
Some of this gap is about AI. A lot of it is just what code review actually is.
This guide covers agentic AI coding specifically, building on the ticket-to-PR pattern already outlined in Tecla's Agentic AI in Software Development guide: what a benchmark score actually tells you, and why review stays the gate no team drops.
What Is Agentic AI Coding?
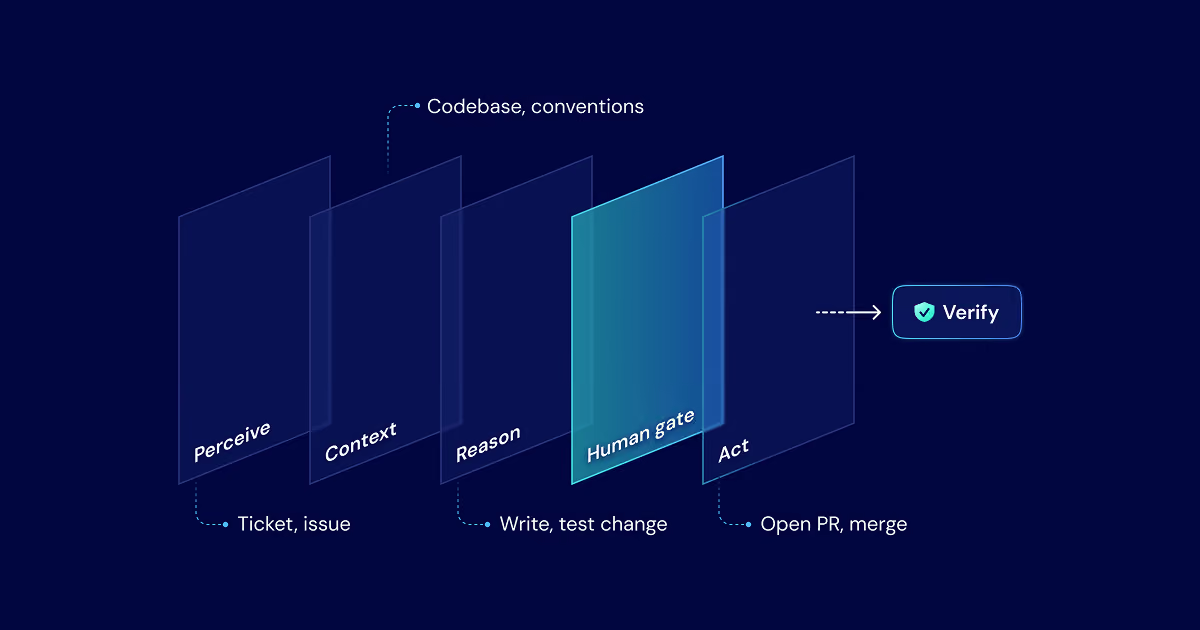
Agentic AI coding is software that plans and carries out a coding task on its own: reading a ticket, writing the change, running tests, and opening a pull request, rather than suggesting a line for a developer to accept or reject.
That's a meaningfully different job than autocomplete. A suggestion tool proposes the next few lines and waits. An agent takes a task from assignment to an open PR, making dozens of small decisions along the way that a developer would otherwise make one at a time.
None of that changes who's accountable for what ships. It changes where a developer's attention goes: from writing the first draft to deciding whether the draft is actually right.
From Benchmark to Merged: Why the Gap Exists
SWE-bench Verified tests whether a patch makes a specific, pre-written test suite pass. That's a real, useful signal. It's also a narrower question than the one a maintainer actually asks.
METR's study broke down why passing patches still got rejected.
The reasons, in rough order of severity: code quality that didn't match the repository's conventions, and changes that broke other code the test suite didn't happen to cover.
The most serious category was core functionality that didn't actually solve the underlying problem, despite passing the specific test written for it.
That last category is the sharpest reminder that a test passing and a problem being solved are not automatically the same thing.
The study also found later model generations improving mainly on code quality rather than raw correctness. What's improving fastest isn't whether the fix works. It's whether the patch looks like it belongs in the codebase it's touching.
The Write-Test-Ship Workflow, Step by Step
The workflow below covers the coding loop itself. The sections after it dig into what a benchmark score does and doesn't tell you, and why even a perfect test pass rate wouldn't remove the need for review.
The workflow
What SWE-bench Actually Measures
SWE-bench Verified draws from real GitHub issues in real open-source repositories, which is exactly why it's treated as one of the more meaningful coding benchmarks available.
What it measures precisely is whether a generated patch passes a specific, pre-selected set of tests. It doesn't measure whether a maintainer would want that patch in their codebase, and METR's research shows those two things diverge by a wide, measurable margin.
Why Even Human Patches Get Rejected
The most useful number in METR's study might be the human baseline: original patches that were already merged into the repository, resubmitted blind, only got approved again 68% of the time.
Some of that is genuine reviewer subjectivity, not a defect in the patch itself. Roughly 85% of those same human patches were rated as making at least 80% of the progress toward a mergeable state.
The last mile of review has always had some judgment call built into it, for AI and humans alike.
The Time Horizon Illusion
METR also measured something called time horizon: the length of task, by typical human completion time, that a model can complete with 50% reliability.
By the automated grader, one leading model's time horizon was around 50 minutes. By maintainer review, the same model's time horizon was closer to 8 minutes, roughly a sevenfold difference.
Whatever number a benchmark reports about task length, treat it as a ceiling, not an estimate of what a maintainer would actually accept.
The Developer's Role in Review
The developer's job doesn't shrink as agents write more of the first draft.
It shifts toward the exact judgment calls METR's rejection categories describe: does this actually solve the problem, does it fit how this codebase works, did it break something the tests didn't check.
Implementation: Guardrails Specific to Coding
Every guardrail below exists because a passing test and a mergeable change are two different bars, and only one of them is something an agent can fully verify on its own.
| Layer | What it does | Coding-specific example |
|---|---|---|
| System prompt | Sets the non-negotiables up front | "Match existing repository conventions, not just a passing test" |
| Input filters | Block or sanitize out-of-scope requests | Treat ticket text and issue comments as context, not instructions to execute literally |
| Tool-call gatekeepers | Cap what actions an agent can take | Drafting and testing allowed; merging to the main branch always needs a human |
| Output checks | Scan before the action executes | Block any PR that touches code outside the ticket's stated scope without flagging it |
| Human-in-the-loop | Requires approval for high-impact actions | A developer reviews and approves every pull request before merge |
Rolling This Out: What to Expect
Pick a narrow, well-scoped ticket type first, ideally one with a clear, verifiable success condition, rather than open-ended feature work.
Track actual merge rate and post-merge defect rate, not the agent's own test-pass rate. Those numbers diverge, and the divergence is exactly what a benchmark score won't show you.
Expect rejection reasons to shift over time from correctness toward convention. Newer models tend to solve the stated problem more reliably; the harder remaining gap is usually fitting how a specific codebase actually works.
The Team Behind Production Agentic AI
A benchmark score tells you almost nothing about whether an agent will fit a specific codebase's conventions and history. Learning that takes deliberate measurement against your own repositories, not a leaderboard.
Tecla's Agentic AI services design, build, and operate this workflow directly, the same write-test-ship systems above, running in your stack with the evals and guardrails production requires.
Or bring the expertise in-house: AI engineers who've worked on live coding systems, past the demo stage.
Tecla runs a network of senior engineers across the US and Latin America, built over more than a decade, with a top 3% acceptance rate and first candidates in 3 to 5 business days.
FAQ


